50 Lessons
 186 Students





RAMANA RAJENDRAN
GOOD COURSE
What is Apache Spark used for? Apache Spark is an open-source, distributed processing system used for big data workloads. It utilizes in-memory caching and optimized query execution for fast queries against data of any size. Simply put, Spark is a fast and general engine for large-scale data processing.Is Apache Spark a database? Apache Spark can process data from a variety of data repositories, including the Hadoop Distributed File System (HDFS), NoSQL databases and relational data stores, such as Apache Hive. ... The Spark Core engine uses the resilient distributed data set, or RDD, as its basic data type.Is Apache Spark dying? The hype has died down for Apache Spark, but Spark is still being modded/improved, pull-forked on GitHub D-A-I-L-Y so its demand is still out there, it's just not as hyped up like it used to be in 2016. However, I'm surprised that most have not really jumped on the Flink bandwagon yet.
 To Register in Course you have to watch at least 30 Second of any lesson
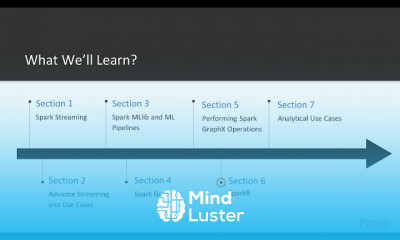
 Master how to set up and configure Apache Spark for large-scale data processing and analytics
Implement efficient data processing workflows using Spark RDDs, DataFrames, and Datasets for big data projects
Optimize Spark performance through caching, partitioning, and query tuning techniques for faster data analysis
Develop scalable Spark applications to handle diverse data sources like HDFS, NoSQL, and relational databases
Apply Spark SQL for complex querying, data transformation, and integration with data warehouses
Utilize Spark Streaming for real-time data processing and live analytics in big data environments
Design and deploy Spark jobs on cloud platforms and distributed computing clusters effectively
Troubleshoot common Spark issues related to performance, memory management, and data consistency
Integrate Spark with other big data tools such as Hadoop, Hive, and Kafka for comprehensive data solutions
Create data pipelines and workflows that automate large-scale data ingestion, processing, and reporting
Implement security best practices in Spark to protect sensitive data during processing and storage
Evaluate Spark's capabilities and limitations to determine its suitability for various big data projects
50 Lessons • 3 h 34 m total

 You must have an
Account
on the platform.
Complete all lessons.
Watch at least 50% of Lesson Duration.
Get your Certificate free 🎉 !
4.3
 (113 reviews)
Overall rating

Be the First One Review This Course
GOOD COURSE
Understandable
very informative and most valuable course
I'm so happy with the presentation of the course material

What is Apache Spark used for? Apache Spark is an open-source, distributed processing system used for big data workloads. It utilizes in-memory caching and optimized query execution for fast queries against data of any size. Simply put, Spark is a fast and general engine for large-scale data processing.Is Apache Spark a database? Apache Spark can process data from a variety of data repositories, including the Hadoop Distributed File System (HDFS), NoSQL databases and relational data stores, such as Apache Hive. ... The Spark Core engine uses the resilient distributed data set, or RDD, as its basic data type.Is Apache Spark dying? The hype has died down for Apache Spark, but Spark is still being modded/improved, pull-forked on GitHub D-A-I-L-Y so its demand is still out there, it's just not as hyped up like it used to be in 2016. However, I'm surprised that most have not really jumped on the Flink bandwagon yet.
Experience the full power of Mindluster with Premium.
No distractions, just pure education.
Cancel your subscription anytime